
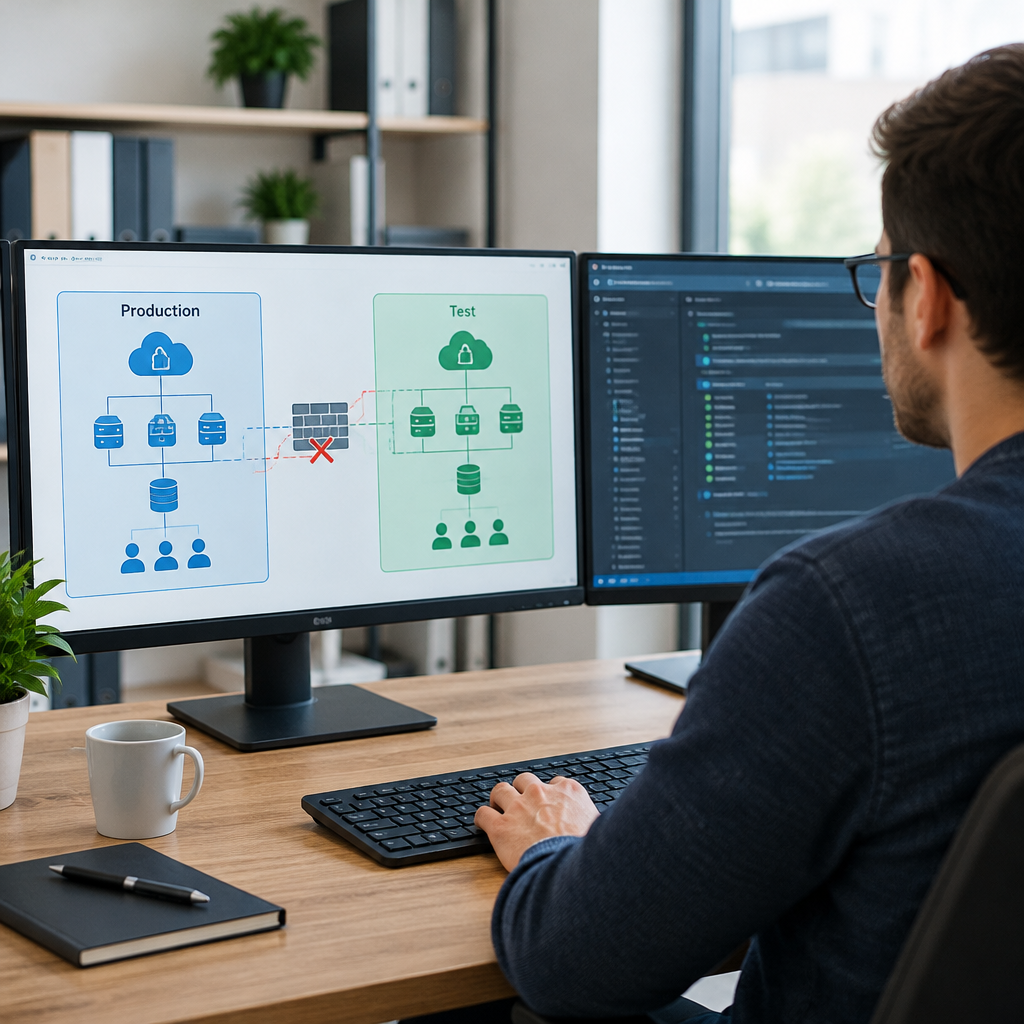
Define the Boundary Before You Create Anything
Separating cloud test data from production information starts with a clear boundary. The boundary should answer three questions: where test data may live, who may access it, and how it can move in and out. Write those rules down before provisioning resources. In practice, that means deciding whether test systems use a separate account, subscription, project, folder, or virtual network, and whether they can reach production services at all. The safest default is a hard separation with no direct trust between test and production identities, networks, or storage locations. If you must share something, restrict it to read-only reference data that cannot identify real people or reveal secrets.
Start with an inventory of the data classes you handle: personal data, credentials, payment-related information, logs, source code, and synthetic fixtures. Mark which items are allowed in test, which require masking, and which must never leave production. Then define a stop rule. Stop if the environment cannot be isolated, if you cannot prove ownership of the data source, or if the team cannot explain how a leaked test copy would be contained. For troubleshooting, keep the boundary visible in naming, tags, and access policy so accidental mixing is easier to detect.
Use Separate Accounts, Identities, and Access Paths
The most effective separation is organizational as well as technical. Use separate cloud accounts or equivalent administrative containers for production and nonproduction workloads when your platform supports it. That makes billing, policy, logging, and access control easier to distinguish. If full account separation is not available, use separate projects or resource groups with distinct identity scopes and explicit deny rules where possible. Never reuse a production administrator account for test work. Instead, create dedicated test identities with the minimum permissions needed to run the application, deploy artifacts, and read only the test datasets they require.
Strong identity separation reduces accidental cross-environment access and helps incident response. Apply multi-factor authentication, role-based access control, and short-lived credentials where your platform allows them. Use separate service principals or workload identities for automation, and ensure they point only to test resources. Review shared secrets carefully; if a pipeline token or API key can reach production and test, treat that as a design flaw. As a reversible change, begin with read-only test access and expand only when a specific workflow requires it. Verification should include a permission check from a test user, an automated pipeline run, and a blocked attempt to reach production assets.
Keep Networks and Endpoints Deliberately Disconnected
Data separation fails if the network still links test and production too freely. Place test workloads in subnets, security groups, or firewall zones that do not route to production databases, internal admin interfaces, or backup systems unless you have a documented exception. Use private endpoints carefully: they should point to test services, not shared production stores. Restrict inbound traffic to the smallest practical set of sources, and prevent outbound access to production management planes unless required for a controlled deployment workflow. DNS can also blur boundaries, so use distinct names that clearly indicate test or production and avoid wildcard records that make environment discovery ambiguous.
Packet filtering, route tables, and service endpoint policies are your first line of defense, but verify them from both sides. Test from a workload inside the test environment and from a user or host that should not have access. If the network design changes, rerun the checks before releasing new data into the environment. Common mistakes include leaving a shared jump host connected to both worlds, reusing a production VPN profile for test, or allowing unrestricted egress because it is convenient during setup. If the application needs temporary access to a production API for validation, make that exception time-limited, narrowly scoped, and easy to revoke.
Create Test Data by Masking, Tokenizing, or Synthesizing
When real production information is not necessary, prefer synthetic data. Synthetic records can preserve format, relationships, and edge cases without carrying real identities or confidential values. If realistic behavior is needed, use masked or tokenized copies of production data, but only after confirming that the masking process removes all direct and indirect identifiers that matter to your policy. Good masking preserves the shape of the data while breaking the ability to map it back to a real person or account. Tokenization can be useful when applications need stable references across multiple tables or services, but the token vault or mapping service must remain separate from the test environment and tightly controlled.
Before using any transformed data, verify that the transformation covered all fields, including free-text notes, filenames, logs, and attachments, because sensitive values often hide there. Check referential integrity, date ranges, and special characters so the test set still exercises the application correctly. A common mistake is assuming that removing names is enough; addresses, account numbers, device IDs, or combinations of quasi-identifiers may still expose someone. Make masking a reversible administrative process only in production, not in test. In test, the goal is usability without re-identification risk. If you cannot prove that the copy is safe, do not promote it into a shared test space.
Use Storage Rules, Encryption, and Lifecycle Controls
Cloud storage is a frequent point of accidental mixing because objects, backups, snapshots, and exports often outlive the application that created them. Put test and production data in separate buckets, containers, shares, or volumes whenever possible. Apply separate encryption keys or key aliases so a storage mistake does not automatically expose both environments. Make sure the key policy matches the data policy: test applications should not use the same long-term secrets as production workloads. Add lifecycle rules to expire temporary exports, old snapshots, and staging copies so forgotten files do not become hidden production mirrors.
Label data clearly through object tags, prefixes, folder names, and metadata, but do not rely on labels alone. Labels help operators, yet real isolation depends on permissions and path design. Confirm that backup jobs, sync tools, and data export scripts point to the intended target and not to a default location inherited from production. Reversible changes are especially useful here: first copy a noncritical sample into the test store, validate permissions, then expand only after the path is proven. Watch for common mistakes such as broad sharing links, public buckets, or mounted shares that inherit permissions from the wrong parent. If a storage location cannot be made private by design, it should not hold test copies of sensitive data.
Build Pipelines That Know the Difference
Continuous integration and deployment tools can accidentally cross the boundary if they use the same secrets, variable sets, or artifact repositories for every environment. Give test and production separate pipeline variables, secret stores, deployment targets, and approval paths. A safe pipeline should be able to build the same application artifact for both environments while still resolving test-only data sources when it runs in test. That requires environment awareness in configuration, not hardcoded addresses or shared credentials buried in scripts. Store configuration outside the code when practical so you can change the destination without editing the application itself.
Treat pipeline access as a privileged path. A build job that can write to production should be exceptional, not normal. For troubleshooting, log which environment the job intended to target, which identity it used, and which resources it touched. Verify the result by running a dry run, then a limited deployment, then a full deployment only after the audit trail matches expectations. Common mistakes include copying a production pipeline to create a test pipeline without changing the secret source, or using a single artifact repository that allows test jobs to overwrite trusted production builds. If the artifact integrity cannot be validated, stop and inspect the promotion process before any further release steps.
Monitor, Audit, and Rehearse Recovery
Hypothetical example for practice, not a real case.
Separation is not complete until you can detect when it breaks. Turn on audit logging for access, changes, data exports, and permission grants in both environments. Route logs to a location that test workloads cannot alter. Review alerts for unusual reads, bulk downloads, cross-account role assumptions, and failed access attempts that may indicate misconfiguration. If your platform supports it, use policy checks or guardrails to block clearly unsafe actions, such as creating a public storage object or attaching a production role to a test instance. These controls are defensive, but they should be paired with human review for high-risk changes.
Rehearse recovery with a controlled, authorized scenario. For example, restore a masked test dataset into a fresh test environment and confirm that the application starts, the records are readable, and no production secrets appear in configuration or logs. Hypothetical example: a team clones a staging database into a disposable test project, runs validation scripts, then destroys the copy after confirming that the restore point contains only masked customer IDs and no active payment tokens. The stop condition is simple: if the recovery step introduces real production identifiers, pause the exercise and purge the copy. Keep a rollback checklist so accidental cross-environment writes can be reversed quickly and with evidence.
Maintain the Separation as the System Changes
Separation degrades over time unless it is part of routine change management. Every new integration, third-party tool, developer shortcut, or support workflow should be checked against the original boundary. When teams add a new cache, analytics sink, or support export, they often forget that data may now move to another service with its own retention and access rules. Update the inventory, labels, and approvals whenever the architecture changes. If an application starts needing production reference data in test, reconsider the design before granting broader access; often a smaller sanitized replica or a one-way export is enough.
Use periodic reviews to confirm that test and production still differ in account structure, network routes, secrets, backups, and logging destinations. Look for drift caused by manual fixes, emergency access, or temporary exceptions that were never removed. A good review ends with specific actions: remove unused shared credentials, rotate keys that touched both environments, delete stale copies, and document who owns each exception. A practical stop condition is this: if you cannot explain why a test system needs a particular production dependency, treat that dependency as suspect until proven necessary. The goal is not perfect bureaucracy; it is a durable, auditable separation that keeps test activity useful without endangering live information.
Post a Comment