
What General Availability Changes for Private Origins
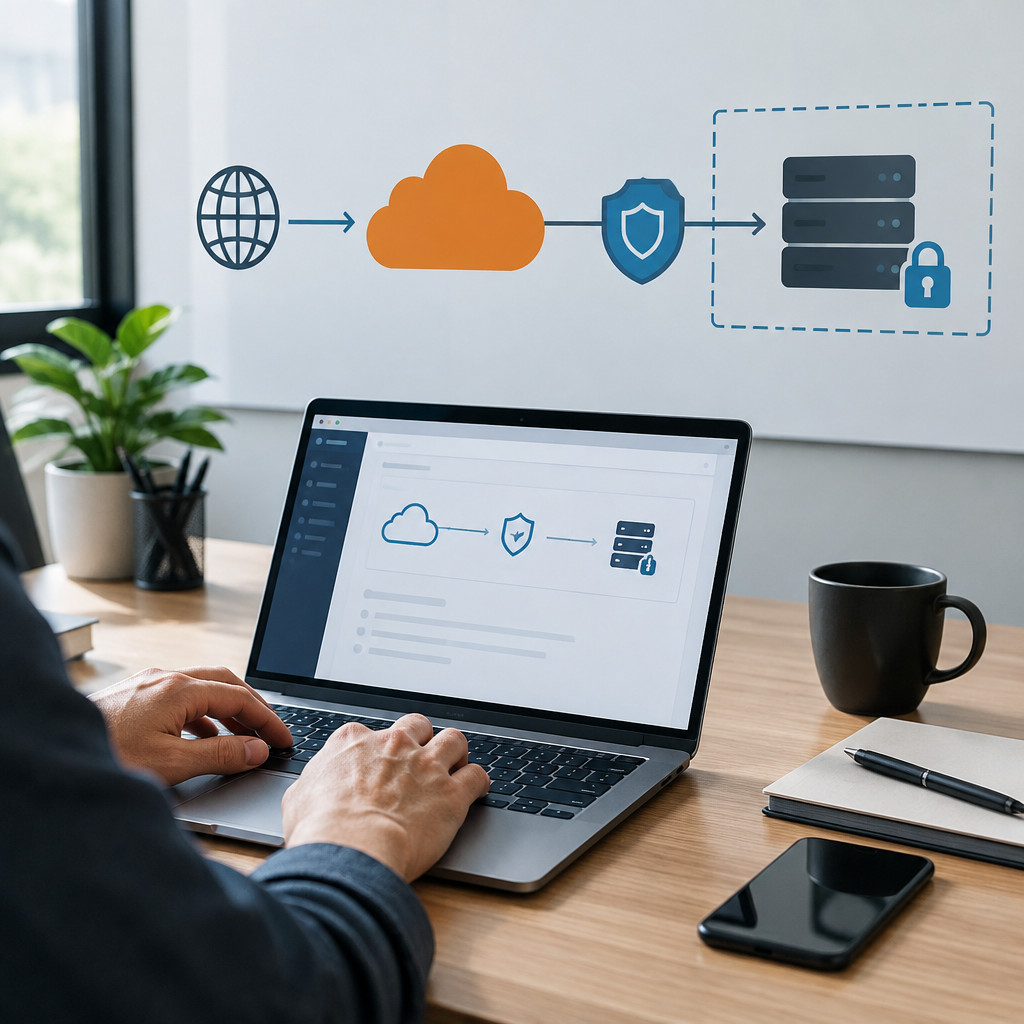
Cloudflare says its services for private origins are now generally available, which matters for teams that want to keep an application endpoint off the public Internet while still serving external users. The practical shift is simple: instead of exposing an origin address directly, you point a proxied DNS record at a private IP and let Cloudflare reach that origin through an existing Cloudflare One connection. For network operations teams, that means the connectivity model is no longer a special exception. It becomes a supported path that can fit into standard change control, access review, and service ownership workflows.
The source also notes that the origin remains private while WAF, caching, bot management, and Workers continue to function as they do for public origins. That is the key operational implication. You are not trading away application-layer controls just because the backend is private. Still, the general availability announcement should be read as a capability statement, not a promise that every deployment is effortless. Teams should verify their own routing, identity, DNS, and origin dependencies before switching production traffic. The safe approach is to treat this as an architecture option that needs testing, rollback planning, and clear ownership, not as a one-click replacement for existing network design.
Decide Which Services Belong Behind a Private Origin
The best candidates are services that should not be directly reachable from the Internet but still need controlled access from customers, partners, or internal agents. Cloudflare’s source explains that the capability was built for internal APIs, AI agent backends, MCP servers, and operational tools that were not designed to face the Internet. That framing is useful for planning. If a service has a narrow consumer set, a sensitive control plane, or a business need for inbound requests without public exposure, it is worth evaluating. If a service is already public by design, this pattern may add complexity without enough benefit.
Before changing anything, classify the traffic path end to end. Identify who initiates requests, which hostnames are involved, what authentication the application already uses, and whether any upstream systems expect the origin to present a public address. Then check whether the origin can be reached only through your Cloudflare One connection, because that is the path Cloudflare describes. If a service depends on direct Internet access from unrelated systems, or on ad hoc troubleshooting from multiple third parties, document that carefully. In many cases, the right answer is partial adoption: move only the private backend components behind this model and leave truly public endpoints on a separate path.
Prepare DNS, Network Access, and Ownership Before Cutover
A practical rollout starts with inventory. Confirm the private IP or internal address space for the origin, the hostname that will be proxied, and the operational owner of each side of the connection. Because Cloudflare reaches the origin over your existing Cloudflare One connection, your network team should verify that the path is already established and monitored. If the tunnel, routing policy, or access control is unclear, resolve that first. The most common failure during cutover is not application logic; it is an incomplete understanding of how packets are supposed to reach the backend once the public route is removed.
Next, stage the DNS change carefully. Use a controlled window, lower risk where your change process allows it, and keep a rollback plan that restores the previous record or traffic path if the application does not behave as expected. Verify the hostname, certificate expectations, and origin health checks before exposing users to the new route. You should also document who can authorize reversal if requests start failing. The stop condition is straightforward: if the origin cannot be reached reliably through the intended private path, pause the migration and fix the underlying connectivity rather than trying to compensate with ad hoc exceptions.
Preserve Security Controls Instead of Rebuilding Them
One advantage of this model is that security controls remain available at the edge while the origin itself stays private. Cloudflare states that WAF, caching, bot management, and Workers work for private origins in the same way they do for public origins. For operations teams, that means you can keep enforcing policy at a familiar control point while reducing direct exposure of the backend. The result is not automatic security, however. You still need a clean application trust model, reliable authentication, and a clear decision about which requests should be blocked, challenged, transformed, or passed through.
Treat this as layered defense. Use WAF to filter obvious abuse, bot management where automated traffic is a concern, and Workers only when you have a deliberate edge-processing need. Keep the origin hardened as though it might eventually be probed, even if it is not publicly reachable. Private placement reduces exposure, but it does not remove the need for patching, least privilege, logging, and incident response. If your organization relies on direct origin access for debugging, create an approved alternative process instead of opening the backend back up. That preserves the benefit of the private design while still supporting operations and support workflows.
Test with a Hypothetical Internal API Before Production
Hypothetical example for practice, not a real case.
Hypothetical example: suppose an owned internal API serves a partner portal and is reachable only through a Cloudflare One connection. The team could first point a nonproduction proxied DNS record at the private IP and confirm that Cloudflare can reach the service without exposing the origin publicly. Then the team would validate that authenticated requests still succeed, that the application logs show the expected source pattern, and that the response path remains stable under normal load. This is the point to test a safe rollback as well, so the team knows exactly how to restore the former route if anything behaves unexpectedly.
In the same hypothetical environment, the team could verify that existing edge protections still operate as intended. For example, a known bad request pattern should still be blocked by policy, and a legitimate request should still reach the application once it passes checks. If a Worker is part of the workflow, confirm that its logic is still applied where intended and that it does not alter headers or routing in ways the backend cannot handle. The goal is not to prove every edge case at once. The goal is to establish that the private-origin path works, that control points are effective, and that the migration can be reversed cleanly.
Troubleshoot Connectivity Methodically, Not by Guessing
When the origin does not answer as expected, work from the outside in. Start with DNS resolution, then confirm that the hostname is proxied, then verify the path between Cloudflare and the private origin through Cloudflare One. After that, inspect origin reachability, application listener status, and any internal firewall rules that could be blocking the request. Because the source does not provide a command sequence or UI path, consult your vendor documentation for the exact checks in your environment. The important habit is to separate name resolution problems from transport failures and from application errors so you do not chase the wrong layer.
Common mistakes include pointing the wrong hostname at the private IP, assuming the origin is reachable when the private route has not been validated, and changing multiple variables at once during a cutover. Another frequent issue is overlooking dependency paths such as upstream databases, identity providers, or internal APIs that the origin needs in order to respond correctly. If symptoms are intermittent, do not assume Cloudflare itself is the cause; check whether the backend is timing out or whether an upstream control is rate limiting requests. A useful stop condition is clear: if you cannot isolate the failure to a specific layer, freeze the change, collect logs, and restore a known-good state before proceeding.
Plan Rollback, Monitoring, and Change Control
Private-origin deployments work best when they are reversible. Before production cutover, write down what must be true for the change to proceed, who approves the change, and what event would trigger rollback. Keep monitoring focused on the path that matters: DNS behavior, edge acceptance, origin health, error trends, and any signs that a backend dependency is struggling. Because Cloudflare’s private-origin capability preserves standard edge features, you should also watch whether those controls are behaving consistently after the switch. If your team lacks clear success criteria, define them before traffic moves, not after a failure occurs.
Change control should include a short recovery sequence that restores the previous record or routing arrangement and a communication plan for users or partner teams if the service degrades. Do not rely on memory during an incident. A private-origin model can simplify exposure management, but it can also make troubleshooting feel less obvious because the backend is no longer directly reachable from the public Internet. That is why logging, runbooks, and a named owner are essential. If the team cannot explain the current routing path in one sentence, the rollout is not ready yet.
Use the Model Where Private Access and Edge Control Both Matter
Cloudflare’s general availability announcement is most relevant to teams that need Internet-facing access to a backend without making that backend public. That includes internal APIs, AI agent backends, MCP servers, and operational tools, but the real lesson is broader: you can combine private transport with familiar edge enforcement. For network operations, this opens a practical middle ground between a fully public origin and a strictly internal service. The architecture is useful when external parties need to reach the application, but the organization still wants the origin to stay inside its own network boundary.
As you adopt the model, keep the evaluation disciplined. Confirm the service is a good candidate, verify the private path, test the edge controls, and document how to back out if anything is unclear. Then review whether the new design improves your operational posture or simply moves complexity elsewhere. The source from Cloudflare says the capability is generally available now, but your own environment still determines whether it is a fit. If the service can be delivered safely through the Cloudflare One connection, and if the team can operate it confidently, private origins can become a durable part of the network operations toolkit.
Post a Comment