
Why Names and Ownership Tags Matter
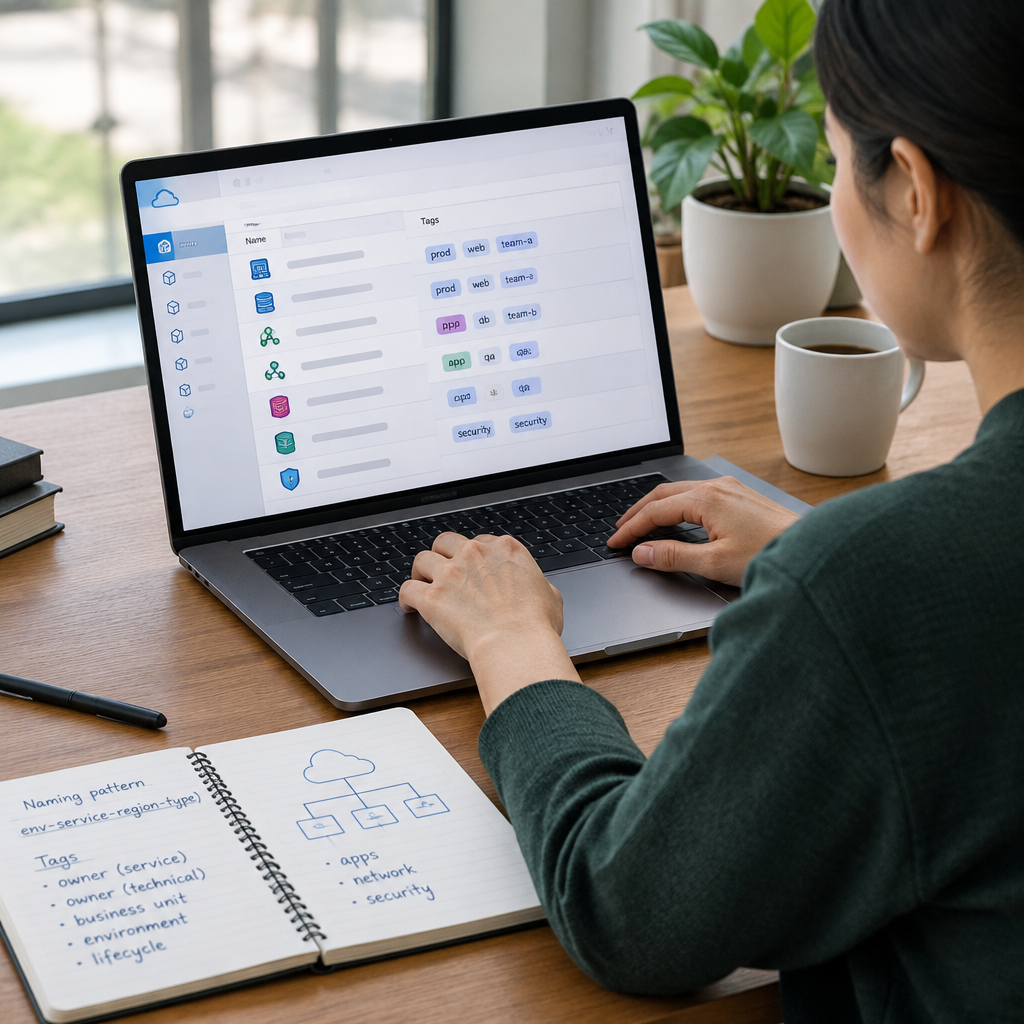
Cloud resources are easier to operate when their names and tags reveal purpose, scope, and responsibility at a glance. A meaningful name helps engineers identify a load balancer, database, network segment, or storage bucket during incidents, while an ownership tag tells them who should respond when something breaks or needs review. This is not just an administrative habit. Clear labels support defensive cybersecurity by making forgotten or exposed resources easier to find, and they support networking and application troubleshooting by reducing ambiguity during outages. They also help cost control, because teams can spot duplicate or orphaned resources faster when those assets are clearly attributed. Good naming is especially valuable in shared cloud environments where multiple projects, environments, and accounts coexist. The goal is not a perfect taxonomy on day one. The goal is a consistent system that survives handoffs, team growth, and emergencies, so the next person can infer what exists without opening ten different consoles or guessing from a default-generated identifier.
Start with a Small, Stable Naming Pattern
A useful naming pattern should be short enough to read quickly and stable enough to survive changes in personnel or tooling. Start by deciding which fields are essential and keep them in the same order. Common fields include application or service name, environment, cloud region or zone, resource role, and a sequence number when needed. For example, a pattern might distinguish between app, dev, and production without forcing every team to encode every possible detail. Avoid names that depend on temporary project slogans, vendor marketing terms, or personal initials that will not make sense later. Also avoid overloading the name with information that already belongs in tags, such as business owner, ticket number, or expiration date. If your organization uses multiple clouds, keep the pattern conceptually similar even if platform limits differ. The practical test is simple: can a responder tell what the resource likely does, and can they say whether it belongs to a production system or a nonproduction one? If not, the name needs work before the resource moves into service.
Use Tags for Ownership, Context, and Lifecycle
Names should identify the thing; tags should explain its business and operational context. Ownership tags usually include a service owner, technical owner, and support group, plus a contact method or on-call alias when your process supports it. Other useful tags indicate environment, cost center, data classification, application name, and lifecycle state such as planned, active, deprecated, or scheduled for removal. Tags are also the right place to record policy-relevant information, such as whether a resource stores sensitive data or participates in a regulated workload. Keep the tag set small enough that people will actually maintain it, and define each tag in plain language. If a tag’s meaning is unclear, it will drift. Where possible, choose values from controlled lists rather than free text, because controlled values make search, reporting, and automation more reliable. If your cloud platform supports inheritance from folders, subscriptions, projects, or resource groups, use that feature carefully and verify what propagates. Ownership should be visible at the resource level for critical assets, even if higher-level grouping carries a default.
Make the Scheme Work Across Networks, Apps, and Security Boundaries
A naming and tagging scheme is most useful when it reflects how systems are actually segmented. Network resources often need names that show their boundary role, such as shared services, application tier, or connectivity layer, because routing, firewall rules, DNS, and VPN paths are frequently debugged by different teams. Application resources benefit from names that tie them to a service boundary rather than a single deployment artifact, so a rolling update does not make the name obsolete. Security teams should ensure the scheme does not leak secrets, internal incident details, or sensitive business information. A public-facing resource name can be seen by more people than the resource itself, so keep it informative but not revealing. For defensive cybersecurity, pair names with tags that support access reviews and asset inventory. If a resource falls outside the normal pattern, stop and ask whether it is an exception that should be documented, or a sign that the architecture is drifting. Consistency across environments helps troubleshooting because responders can recognize patterns immediately when comparing development, staging, and production systems.
Build the Rules Before You Provision Anything
The easiest way to keep naming clean is to define the standard before resources are created. Write a short policy that states which fields are required, which are optional, who approves exceptions, and how names should be formatted. Include examples for the most common resource types, but do not make the policy so long that nobody reads it. Then create a simple checklist for provisioning and change review. The checklist should ask whether the new resource matches the naming pattern, whether required ownership tags are present, whether the environment label is correct, and whether the resource is placed in the right account, subscription, project, or network segment. If you use infrastructure as code, put validation into templates and pipelines so bad names fail early. If you provision manually, use a preflight review before the resource goes live. The practical stop condition is clear: if the resource cannot be named and tagged correctly at creation, pause until the owner information is known. Do not let “we will fix it later” become the default, because later often means never, especially for low-visibility assets.
Verify, Audit, and Correct Without Breaking Services
Once resources exist, verify that naming and tags are actually useful in practice. Start by querying inventory reports or asset lists and checking whether you can find resources by environment, owner, and application without manual guesswork. Review a sample of critical systems and confirm that the named owner is reachable, the support group is current, and the environment label matches reality. When correcting names, be cautious: some cloud resources can be renamed safely, while others are tied to DNS records, certificates, application configuration, or external integrations. Always consult vendor documentation before changing identifiers on live systems. If a name change is risky, use tags, aliases, or documentation updates as an interim step. Record the reason for the change so future responders understand the history. For verification, test one controlled lookup from an operational dashboard or inventory report and confirm that a responder can identify the right team without extra explanation. If that fails, the taxonomy is still too vague. Stop and revise the standard instead of adding more fields to compensate for a weak structure.
Common Mistakes That Create Confusion
A common mistake is using names as a dumping ground for every possible detail. Long strings become unreadable, and the most useful information gets buried. Another mistake is encoding ephemeral facts, such as a ticket number or migration phase, directly into the primary name. Those details belong in change records or lifecycle tags, not in the core identifier. Teams also get into trouble when they use different abbreviations for the same concept, such as dev, development, and devel, or when they let individual engineers invent local conventions. Inconsistent spelling is especially harmful because search and automation depend on exact matches. A further mistake is confusing ownership with creation. The person who provisioned a resource is not always the person who should receive alerts or approve changes. Finally, do not rely on tags alone if the platform or process does not enforce them. Unlabeled resources tend to multiply quietly, especially in test environments and shared network spaces. The safer approach is to treat missing ownership as an operational defect, not a cosmetic issue, and to fix the process that allowed the gap.
A Practical Rollout Plan for Existing Environments
Hypothetical example for practice, not a real case.
For an existing cloud estate, roll out changes in phases so you do not disrupt active services. Begin with an inventory of the highest-risk and highest-value resources, such as internet-facing systems, production databases, core network components, and identity-related services. Apply the naming standard to new resources first, then progressively remediate old ones where changes are safe. Use a maintenance window for any rename that might affect connectivity, certificates, or application configuration. Where renaming is not safe, add the ownership tags, update documentation, and create a cleanup plan. Track exceptions separately so they do not become permanent habits. A good rollout has a clear end state: resources are searchable, ownership is current, and critical assets follow the standard closely enough that responders can act quickly. The stop condition is also important: if a proposed change risks service stability more than it improves clarity, leave the live name in place and rely on tags plus documentation until a safer migration path exists. Over time, consistency matters more than perfection, because a readable system is easier to secure, troubleshoot, and govern.
إرسال تعليق